What Enterprise Data Needs Before AI Agents Can Take Action
Date
October 5th, 2026
Reading Time
7 mins
Enterprise interest in AI agents is moving faster than the data environments behind them. McKinsey reports that nearly two-thirds of enterprises worldwide have experimented with agents, but fewer than 10% have scaled them to deliver tangible value. More importantly, eight in ten companies identify data limitations as a barrier to scaling agentic AI.
The gap becomes easier to understand when AI moves from retrieving information to taking action. At that point, inaccurate or outdated data is no longer only an information problem. It can become an operational problem.
This is where data readiness for AI needs to evolve.
Deloitte's 2026 research found that 72% of surveyed leaders said their organisations lacked unified and accessible data for agentic AI, while 70% reported challenges around trusting and governing agents and 67% cited the cost and complexity of integration. In the same research, only 5% said their business processes were highly prepared for AI agents.
The challenge is not just giving an AI agent access to enterprise data. It also needs the right source, the right context, and clear boundaries around what it can use and what it can do. That makes freshness, permissions, workflow state, metadata, lineage, and monitoring part of the operational foundation, not just supporting data functions.
As agents move closer to real business processes, data needs to be current enough for the decision, trustworthy enough to act on, and governed enough to keep that action within business rules.
For enterprises, the next step is to understand what needs to be taken behind that action.
1. How Data Readiness for AI Changes When Agents Can Take Action
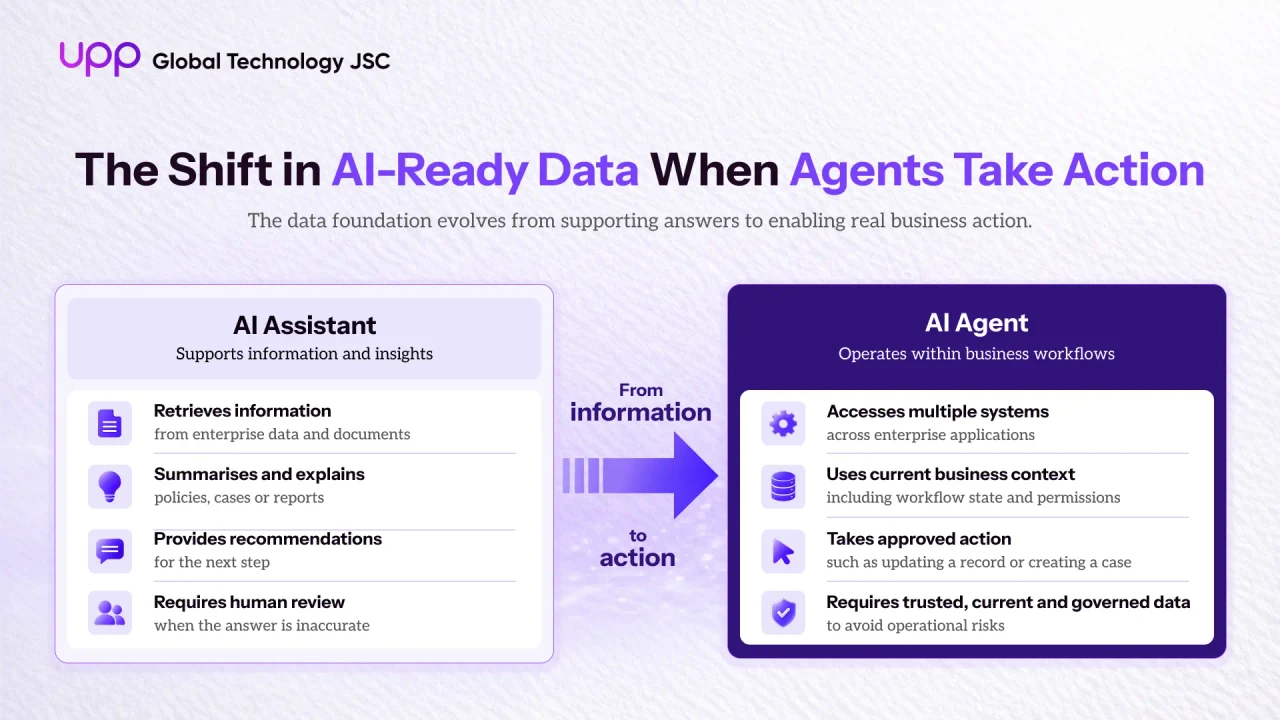
The first stage of data readiness for AI focuses on whether AI can access, understand and trust the information required for a particular use case. That remains important, but an agent that can interact with business systems introduces another requirement: the data environment also has to support the action that follows.
An inaccurate answer from an AI assistant may need to be corrected by a user. An agent working inside an operational workflow can create a different consequence. If it acts on stale account information, misses an approval status or receives the wrong business definition, the problem may propagate into another system before anyone notices.
Operational agents therefore need more than successful retrieval. Research into enterprise data agents increasingly distinguishes analytical workloads, which focus on history and insight, from operational workloads, where accuracy, latency, governance and action become more important.
This does not mean enterprises need an entirely separate data estate for AI agents. It means the existing foundation has to expose data in a form that reflects the current business situation and the rules surrounding it.
That is the deeper layer of data readiness for AI enterprises need to prepare for.
>> Read more: Is Your Enterprise Data AI-Ready?
2. Building the Enterprise Data Layer for AI Agent Action
The operational layer behind an AI agent is not a single database or a new platform added on top of the existing environment. It is the combination of data pipelines, integrations, governance controls and serving capabilities that helps the agent access trusted information, understand the current business state and interact with enterprise systems within clear boundaries.
Data Engineering provides the infrastructure that moves and prepares data. Data Integration connects fragmented sources and keeps information aligned across systems. Data Governance makes that information trustworthy, traceable and secure, while an AI-ready data platform helps deliver governed and current data to AI workloads when it is needed.
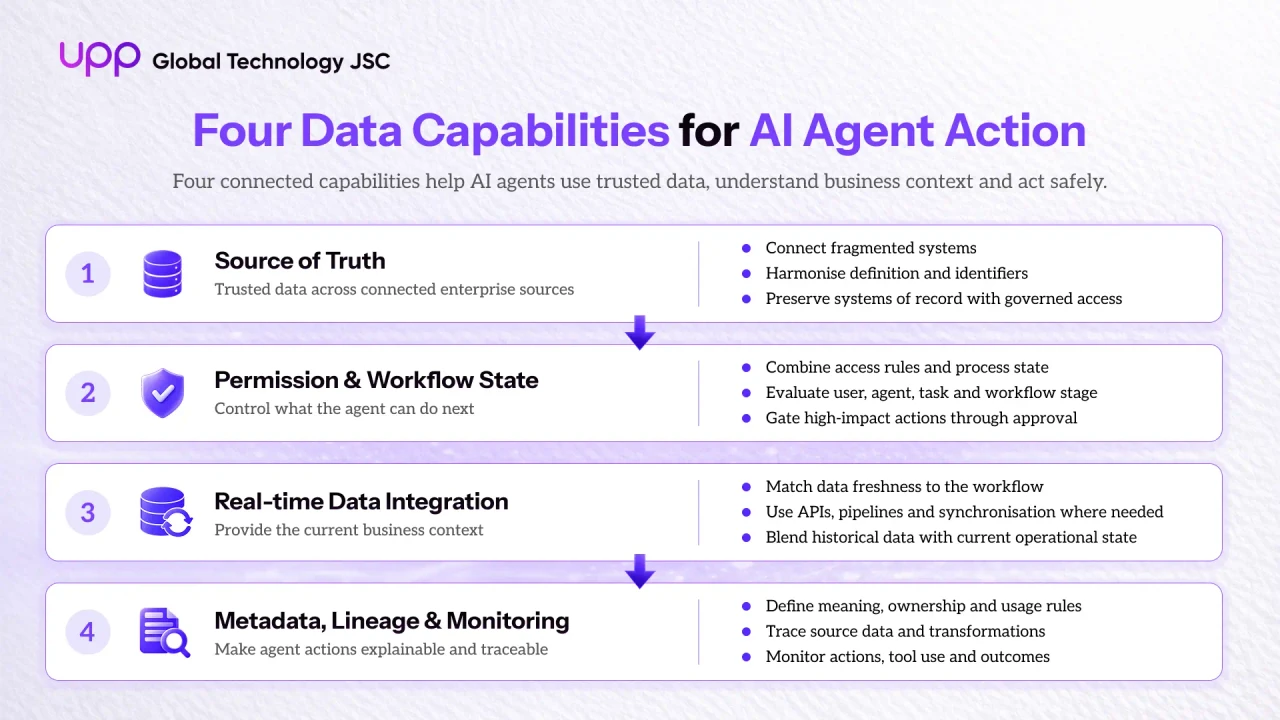
Once AI moves from retrieval to business action, four capabilities become especially important.
2.1. Source of Truth: The Foundation of the Enterprise Data Layer
Before an agent can use enterprise data confidently, it needs a clear source of truth that tells it which information can be trusted for the task at hand.
That becomes difficult when the same customer, product, employee or transaction appears across several systems. CRM may contain one customer status, a billing platform another and a support system a third. Each record may be valid within its own context, but the agent still needs to understand how those records relate and which information should guide the next action.
A strong enterprise data layer helps resolve this by connecting fragmented sources into a more unified and trusted data environment. Multi-source integration brings relevant systems together, while data harmonisation helps align formats and definitions. Master data management can provide more consistent identities and reference information for important business entities such as customers, products or accounts.
This does not mean moving every piece of enterprise information into a single repository. The objective is to make trusted data accessible across existing systems while preserving the role of each source. Depending on the workflow, an agent may retrieve customer information from CRM, transaction data from an operational system and policy context from another governed source.
Source of truth is therefore also about meaning and traceability. Data cataloguing, lineage and quality controls help establish where information comes from, what it represents and whether it is reliable enough for the action being considered.
2.2. Permissions and Workflow State: Control What AI Agents Can Do
Accessing the right operational data is only one part of an agent’s decision process. Permissions and workflow state define what the agent is allowed to do and whether that action is valid at the current stage of the process.
Traditional access controls answer questions such as who can view or modify particular data. AI agents introduce more context because the permitted action may depend on the user, the agent, the task and the current stage of the workflow.
For example, a case that is still open may allow an update. The same update may require approval once the case has been escalated, or become unavailable after the process is closed.
Workflow state therefore needs to be available alongside the business data the agent receives. At runtime, the system should be able to evaluate the request against permissions, security policies and process rules before an action reaches the underlying application. Research on operational data agents describes this as separating AI reasoning from data and action control: the agent can decide what it believes should happen next, while the surrounding system determines whether that action is actually permitted.
Microsoft similarly recommends treating agents as explicit identities, giving them narrowly scoped permissions and controlling access to the tools through which they can retrieve data or change systems. High-impact actions can then be gated through approval or other controls.
2.3. Real-Time Data Integration: Give AI Agents the Current Business Context
Real-time data integration becomes important when changes in operational systems can alter the next action. Rather than making every source real time, enterprises can identify the data points where latency creates business risk and design synchronisation accordingly.
But not every AI workload needs real-time data.
A policy assistant may work well when documents are synchronised daily. An inventory agent deciding whether an order can be fulfilled may need much fresher information. What matters is whether the data is current enough for the decision being made.
For example, an order workflow might use relatively stable product information from one platform while retrieving current inventory and fulfilment status through operational APIs. The important point is not that every source follows the same architecture, but that the agent receives the appropriate level of freshness for each part of the task.
This is also why an AI-ready data platform may combine different serving patterns. Warehouses and lakehouses can support trusted historical data, APIs can expose current application state, and real-time pipelines can synchronise fast-changing information. The data architecture should follow the workflow rather than force every AI use case through the same path.
2.4. Metadata, Lineage and Monitoring: Make Agent Actions Traceable
Even trusted and current data can be misused when its meaning is unclear.
The data layer therefore needs metadata, lineage and monitoring to clarify what the data means, trace where it came from and show how the agent used it during an action.
Metadata provides the definitions around that information: what a field represents, who owns it, how it relates to other data and which rules apply to its use. If several teams calculate a metric differently, those definitions help prevent the agent from treating similar labels as the same business concept.
Lineage answers a different question: where did this information come from? When an agent's action needs to be reviewed, teams should be able to trace relevant data back through its source and transformations. Data cataloguing, lineage and quality management provide this visibility within the data foundation.
Monitoring then follows what happens at runtime. Once agents call tools and interact with operational systems, enterprises need visibility into what was accessed, which action was attempted and whether it succeeded. Deloitte reports that around 80% of surveyed organisations currently lack mature agent governance capabilities such as clearly defined decision boundaries, real-time behavioural monitoring and complete action audit trails.
These capabilities serve different purposes but work together: metadata explains the data, lineage traces its origin and monitoring records how the agent used it.
>> Read more: Traditional Data Architecture vs Agentic Data Architecture
3. How These Capabilities Work Together in an AI-Ready Data Platform
The four capabilities above should not become four disconnected technology projects.
An AI-ready data platform brings them together through a common data foundation. Data engineering creates reliable pipelines and storage. Data integration connects enterprise sources and keeps important information synchronised. Data governance manages quality, access and traceability. Serving and retrieval components then expose trusted information to AI workloads through the most appropriate path.
Depending on the use case, that environment can include data warehouses, data lakes, operational APIs, real-time data serving, vector databases or feature stores. The purpose of the platform is not to introduce every possible component. It is to make trusted enterprise information reusable across multiple AI applications while preserving the controls already required by the business.
This also addresses a common scaling problem. If every proof of concept creates its own connectors, data copies, permissions and retrieval logic, the organisation accumulates another layer of silos. Reusable integration patterns, governed data assets and common serving capabilities give future agents a stronger starting point.
4. How UPP Builds an AI-Ready Data Platform for AI Agents
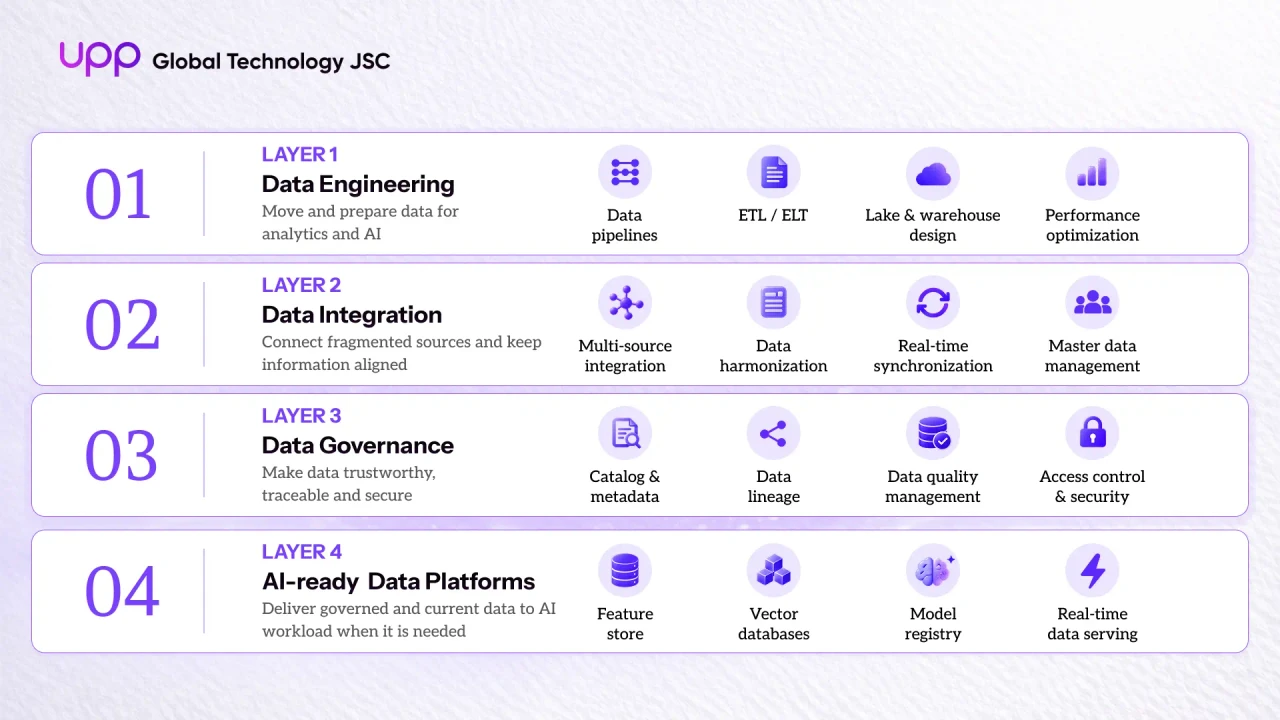
UPP approaches Enterprise AI as an integration problem across data, AI, systems and workflows, rather than treating the model as an isolated solution. The data foundation is established first so AI can operate on information that is connected, governed and suitable for production workloads.
Data Engineering provides the underlying infrastructure through pipeline architecture, ETL/ELT development, data lakes, data warehouses and performance optimisation. Data Integration connects fragmented sources through multi-source integration, data harmonisation, real-time synchronisation and master data management. Data Governance adds cataloguing, lineage, quality management, access control and security. Together, these capabilities create a stronger base for an AI-ready data platform with governed architecture and real-time data serving where the workload requires it.
The next step is connecting that foundation to the workflow. AI agents may need to interact with CRM, helpdesk applications or other operational platforms rather than working beside them. UPP's AI Integration approach supports agents that execute multi-step tasks across these environments while retaining human review and escalation where appropriate.
Operations continue after deployment. Monitoring, decision logging and audit readiness help enterprises understand whether AI remains reliable as data, systems and business conditions change. This creates a continuous path from the underlying data foundation through AI integration to ongoing AI operations rather than treating production deployment as the end of the project.
The architecture should still begin with the use case. An agent handling support requests, an AI workflow processing healthcare information and an education assistant will not need the same sources, latency, access rules or approval points. The foundation should provide shared capabilities without forcing every workflow into the same design.
>> Explore UPP’s Data Services
5. From AI-Ready Data to Reliable AI Action
AI agents do not make the existing enterprise data foundation obsolete. They make weaknesses in that foundation harder to ignore.
When AI retrieves information, missing context can lead to a poor answer. When AI can act, the same weakness may affect an operational process. Enterprises therefore need to know which data the agent should trust, whether that information is current, what the workflow allows and whether the resulting action can be traced.
That is the deeper layer of data readiness for AI. The goal is not to prepare every dataset for autonomous use or make every system real time. It is to make the information behind a specific workflow connected, trustworthy, sufficiently current and governed for the action AI is expected to support.
As agent autonomy increases, the model is only one part of that equation. The enterprise data foundation determines whether the agent is acting on the business as it actually exists.
FAQ
1. What does data readiness for AI mean when AI agents can take action?
For AI agents, data readiness for AI goes beyond making information accessible and accurate. The data also needs to be connected to the current business context, governed by clear permissions and reliable enough to support the action the agent is expected to take.
2. What capabilities should an enterprise data layer provide for AI agents?
An enterprise data layer should help AI agents access trusted sources, understand how data from different systems relates, work with sufficiently current information and operate within defined governance controls. It should also support metadata, lineage and monitoring so enterprises can understand how data contributed to an AI action.
3. Why do AI agents need both trusted data and current workflow context?
Trusted data tells the agent which information it can rely on, while workflow context shows what is happening in the business process at that moment. An agent can use accurate data and still make the wrong decision if it does not know that a case has already been approved, escalated or closed.
4. How do data governance, lineage and monitoring support safer AI agent actions?
Data governance controls what information and actions are allowed. Lineage helps teams trace where the data came from, while monitoring provides visibility into what the agent accessed, which tools it used and what happened after the action was attempted.
5. Does an AI-ready data platform require all enterprise data to be real-time?
No. The required level of freshness depends on the business process and the action being supported. Stable information such as policies may not need continuous updates, while inventory, account status or other fast-changing operational data may require real-time integration or more frequent synchronization.
Tags cloud
Newsletter
DISCOVER MORE





























LET’S TALK...
Content delivered to your inbox


ENTER YOUR EMAIL
YOU WANT TO...


Hanoi, Vietnam
Web3 Tower, No. 15, Alley 4, Duy Tan, Cau Giay, Hanoi, Vietnam